MLA Profiling
Profiling MLA attention on H100 reveals reconstruction GEMMs consume 61% of attention-layer time. INT4 quantization should help but doesn't, because the weights fit in L2 cache.
Year
2026
Profiling MLA attention on H100 reveals reconstruction GEMMs consume 61% of attention-layer time. INT4 quantization should help but doesn't, because the weights fit in L2 cache.
Year
2026
Packed INT4 GEMM kernel in Triton for decode-heavy LLM inference with hardware counter attribution and a regime model for when quantization helps. Up to 3.7× speedup on A10G.
Year
2025
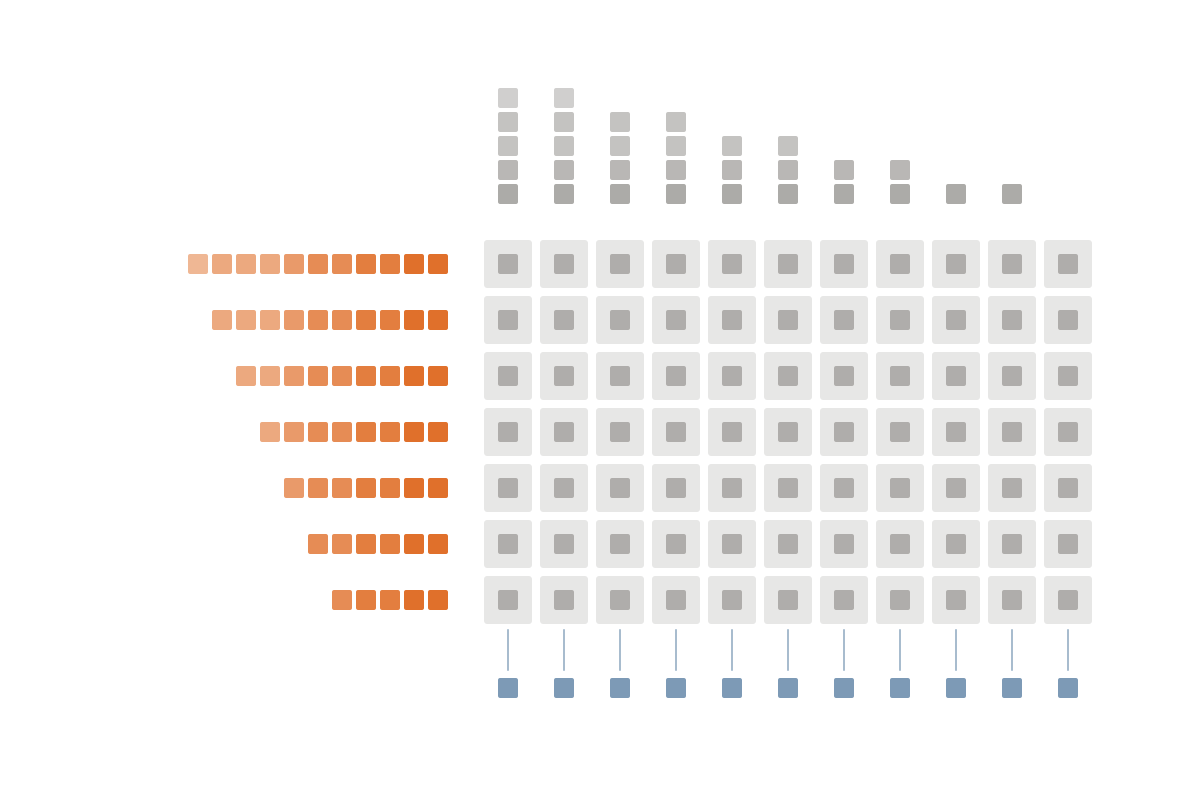
Kernel development and HW/SW co-design for Atalla, a student-built weight-stationary systolic array AI accelerator. FlashAttention mapping, im2col convolution, tiled GEMM, and PyTorch backend integration.
Year
2025
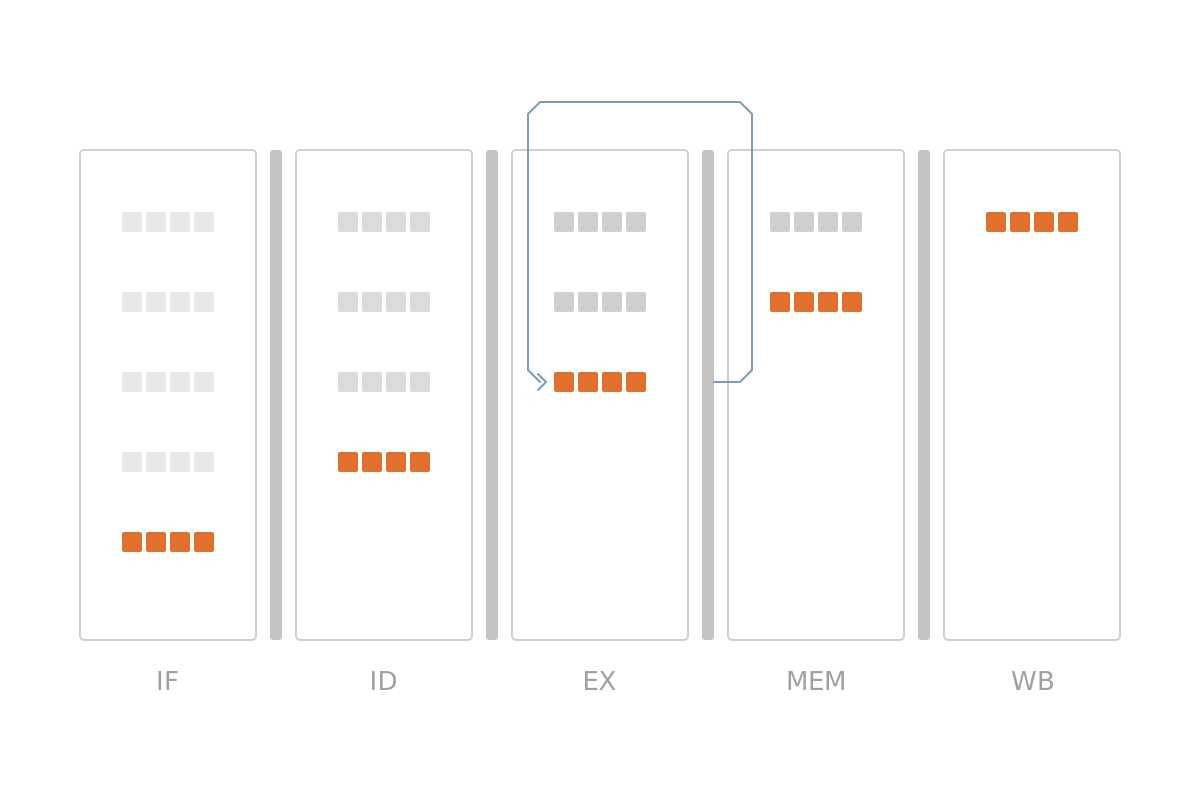
Fully pipelined 5-stage RISC-V processor in SystemVerilog with hazard detection, data forwarding, and a 2-bit branch predictor. Synthesized in Cadence targeting 70 MHz.
Year
2025
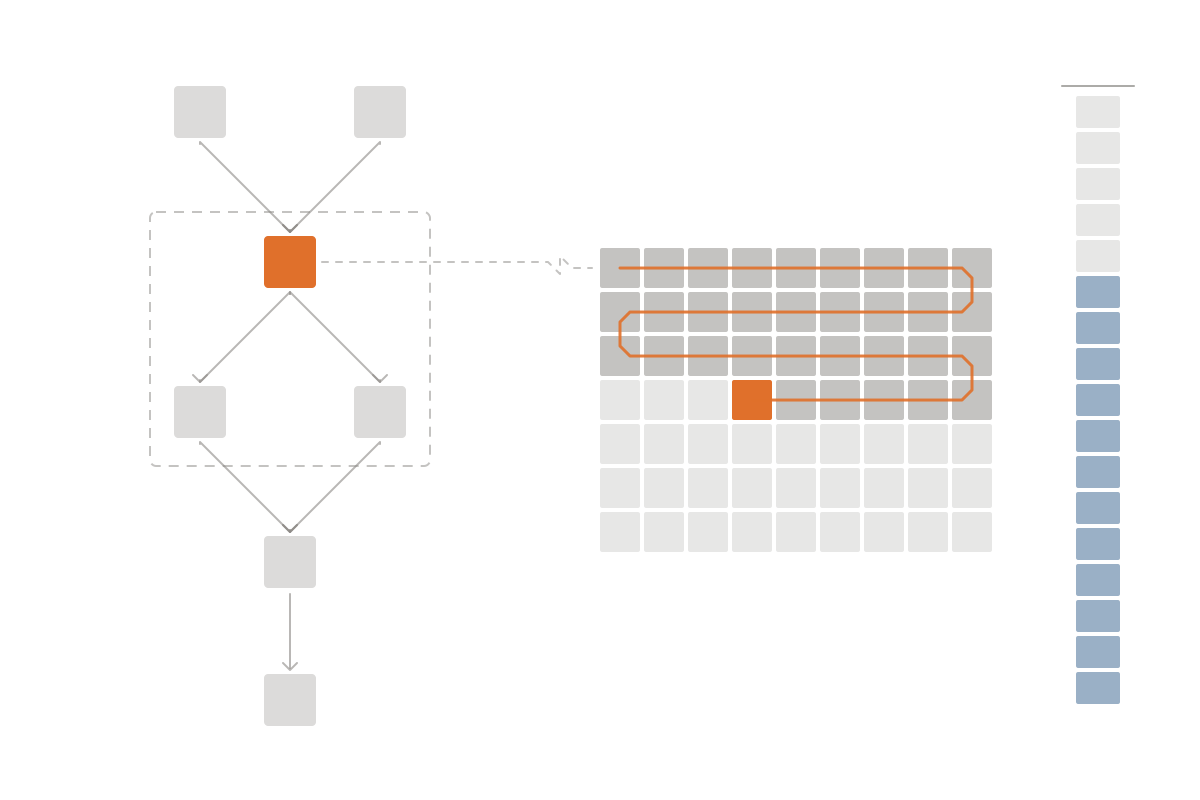
A scheduler for ML accelerator computation DAGs that minimizes latency while respecting tight on-chip SRAM capacity constraints. Google MLSys 2026, Track A.
Year
2026
A fused CUDA kernel implementing DeepSeek Sparse Attention on NVIDIA B200 (Blackwell). FlashInfer AI Kernel Generation Contest, MLSys 2026.
Year
2026
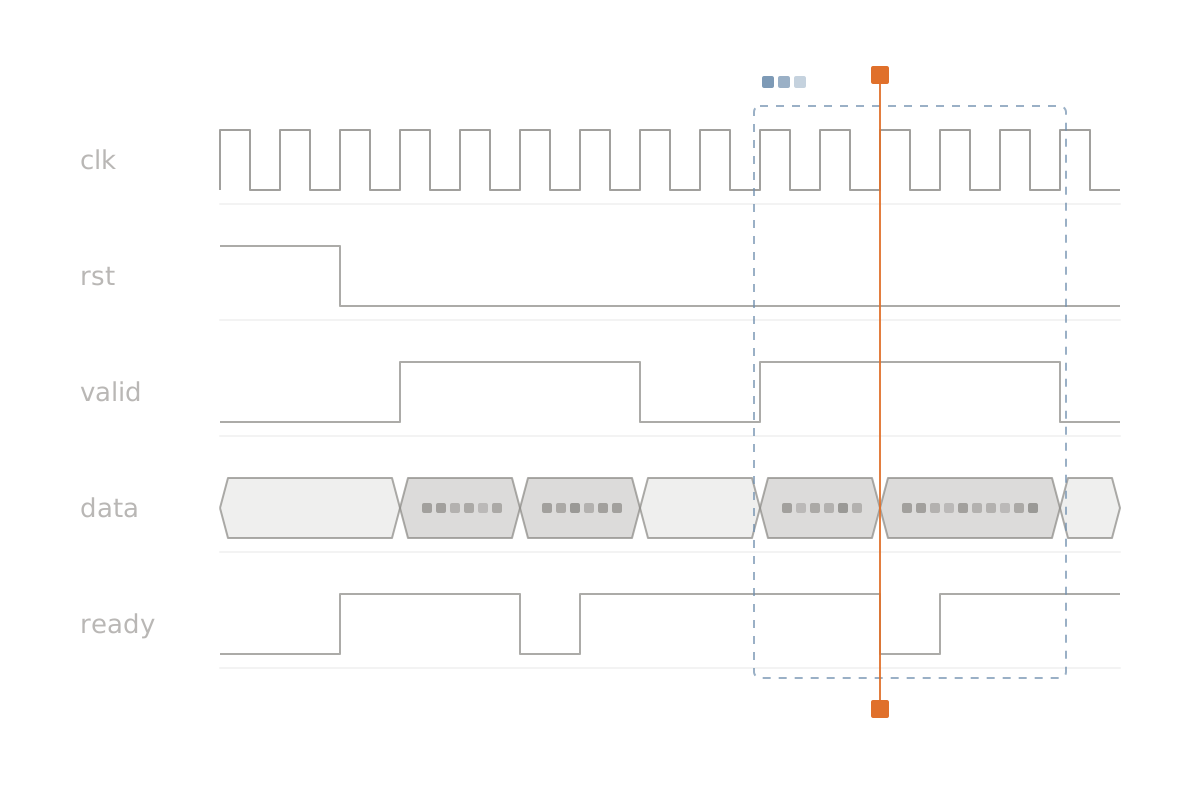
Integrated RTL design verification tool for testbench generation, script and trace analysis with multi-agent collaboration for accelerated RTL development.
Year
2025
view projectMLA Profiling2026Profiling MLA attention on H100 reveals reconstruction GEMMs consume 61% of attention-layer time. INT4 quantization should help but doesn't, because the weights fit in L2 cache.view projectGraph Scheduling2026A scheduler for ML accelerator computation DAGs that minimizes latency while respecting tight on-chip SRAM capacity constraints. Google MLSys 2026, Track A.view projectSparse Attention2026A fused CUDA kernel implementing DeepSeek Sparse Attention on NVIDIA B200 (Blackwell). FlashInfer AI Kernel Generation Contest, MLSys 2026.view projectTiny-GEMM2025Packed INT4 GEMM kernel in Triton for decode-heavy LLM inference with hardware counter attribution and a regime model for when quantization helps. Up to 3.7× speedup on A10G.view projectAtalla Kernels2025Kernel development and HW/SW co-design for Atalla, a student-built weight-stationary systolic array AI accelerator. FlashAttention mapping, im2col convolution, tiled GEMM, and PyTorch backend integration.view projectRISC-V CPU2025Fully pipelined 5-stage RISC-V processor in SystemVerilog with hazard detection, data forwarding, and a 2-bit branch predictor. Synthesized in Cadence targeting 70 MHz.view projectVeriGen2025Integrated RTL design verification tool for testbench generation, script and trace analysis with multi-agent collaboration for accelerated RTL development.